
Research / Firebolt-VL
Firebolt-VL
Efficient vision-language understanding through cross-modality modulation.
What this project does
Firebolt-VL is a lightweight vision-language model aimed at fast multimodal reasoning under practical deployment constraints — the case where a model has to answer questions about an image on hardware that is not a research cluster.
Why it matters
Most vision-language work reports quality at a scale that assumes abundant compute. The gap between that setting and a model someone can actually run is where a lot of useful applications fall through. Firebolt-VL is an attempt to work in that gap deliberately rather than treating efficiency as an afterthought.
Method overview
The project explores cross-modality modulation: letting signals from one modality condition how the other is processed, rather than fusing the two representations late and hoping the combination carries the right information.
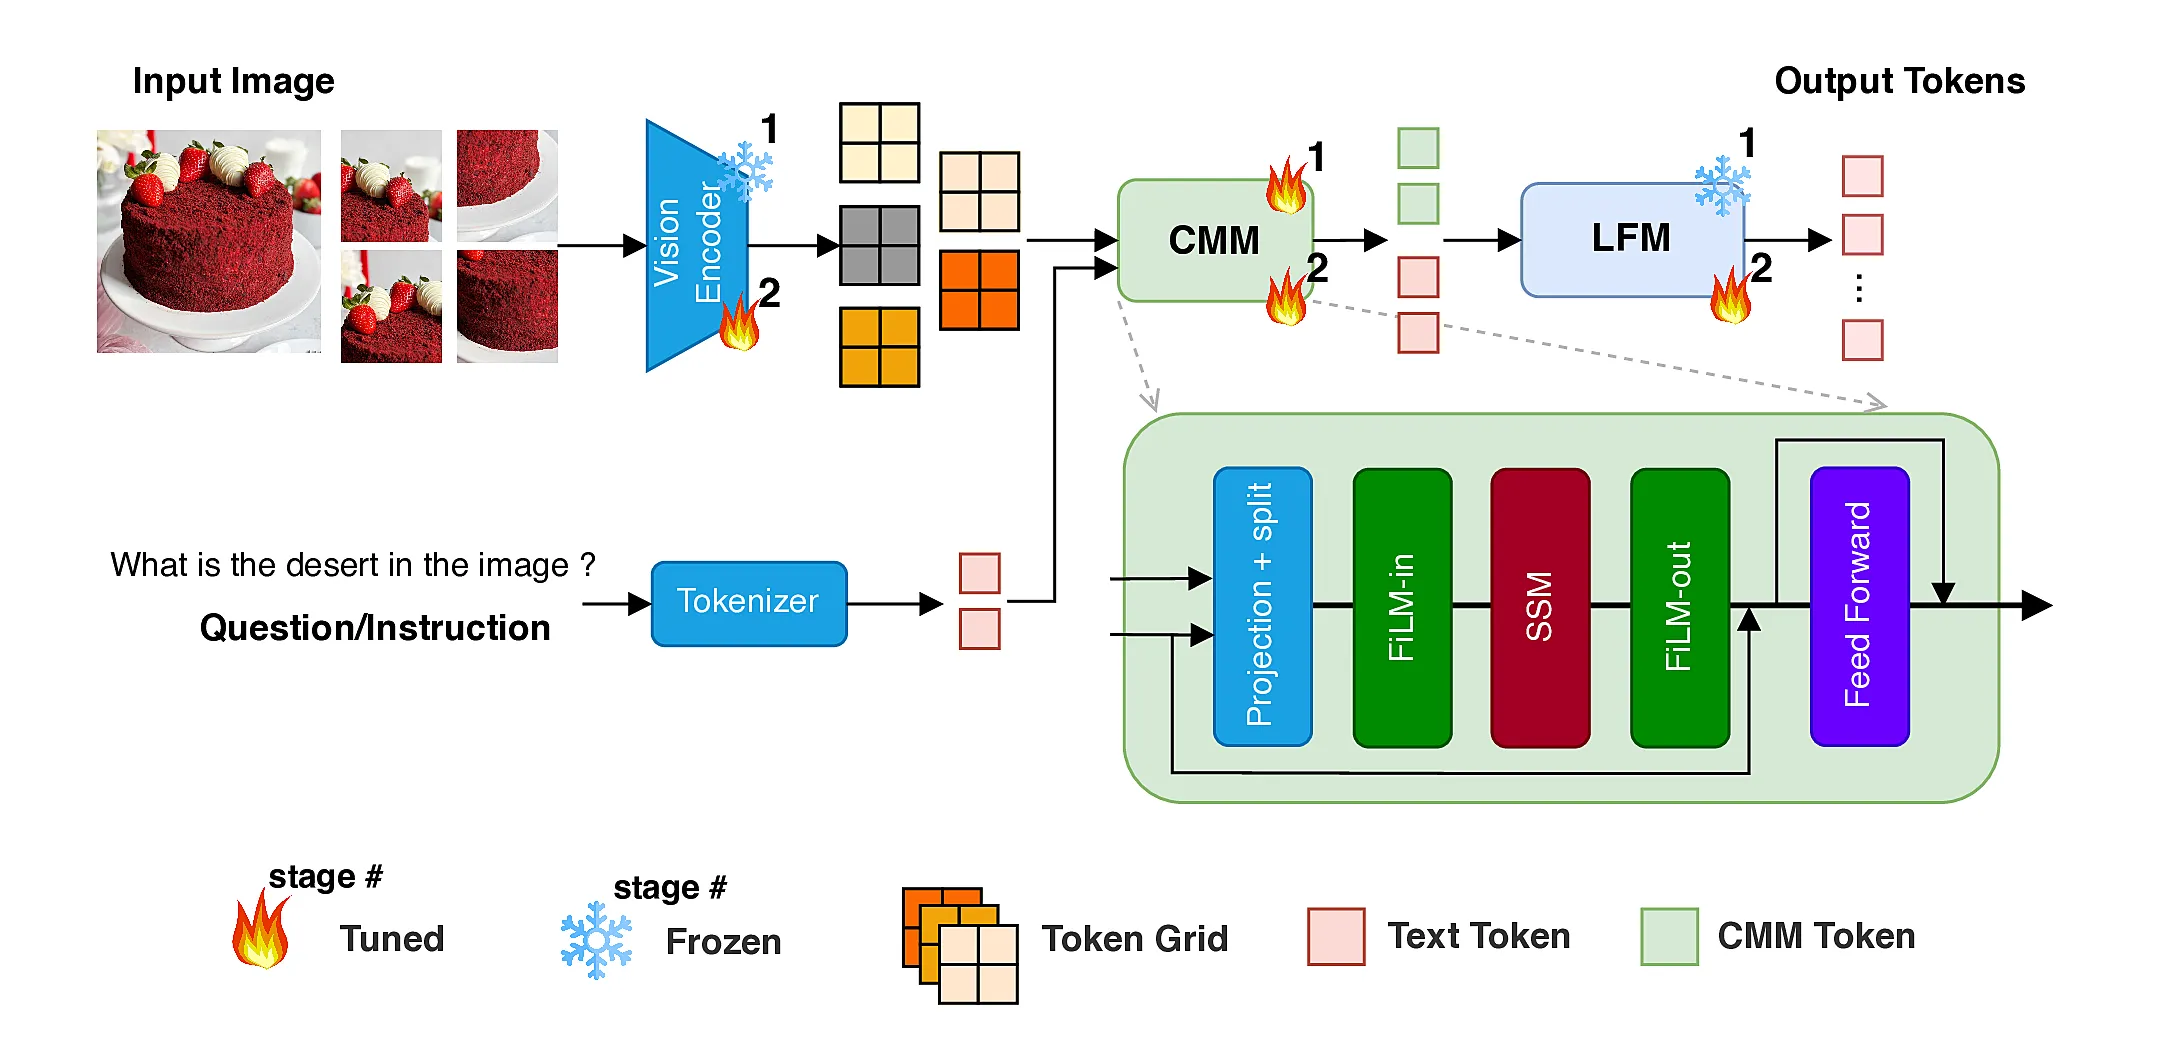
The published architecture combines a SigLIP vision encoder, the lightweight Cross-modal Modulator (CMM), and an LFM2-350M-based language decoder. CMM uses token-grid correlation, Top-K grid selection, FiLM conditioning, and a structured state-space model to connect visual and text representations without a heavy cross-attention fusion stack.
Current status
This project remains in active development, with Firebolt-VL V2 underway. Code
is available through the lab’s GitHub repository. The current checkpoint is
published under the project lead’s huyquoctrinh Hugging Face namespace—not the
OpenRB-Lab organization—and is labeled Apache-2.0.
Code and checkpoint
Download the published checkpoint with the Hugging Face client:
from huggingface_hub import snapshot_download

checkpoint_dir = snapshot_download("huyquoctrinh/FireboltVL")
The model card notes that inference code may require the Firebolt-VL repository’s custom model implementation. Review the repository and model card together before running the checkpoint.
Intended use
- Research on efficient vision-language understanding and fine-grained visual grounding.
- Reproducing and extending the published Firebolt-VL evaluations.
Known limitations
- The project is under active development and has not been through a documented release review.
- No evaluation results have been published on this site yet.
@article{trinh2026fireboltvl,
  title={Firebolt-VL: Efficient Vision-Language Understanding with Cross-Modality Modulation},
  author={Trinh, Quoc-Huy and Abdullahi, Mustapha and Zhao, Bo and Jha, Debesh},
  year={2026},
  eprint={2604.04579},
  archivePrefix={arXiv},
  primaryClass={cs.CV},
  url={https://arxiv.org/abs/2604.04579}
}